Microsoft, America’s Air Traffic Control Crisis, and the Hidden Vulnerability of the Digital Economy
By Arturo Duran | November 14, 2026
Technology, Power & the Future — Article II
Two major disruptions. Two different technological systems. One fundamental question: Have we built an economy that is more interconnected than it is resilient?
Executive Summary
Within approximately 24 hours, two major disruptions exposed different vulnerabilities in the digital infrastructure supporting modern economies.
On November 12, Microsoft experienced a widespread disruption affecting cloud-based productivity, communications and enterprise services.
On November 13, the United States Federal Aviation Administration (FAA) ordered a nationwide ground stop after instability affected telecommunications systems supporting air traffic control.
The two incidents were not technically connected, according to available reporting. Yet they raise remarkably similar questions about infrastructure dependency, aging technology, operational concentration, redundancy and the ability of critical systems to recover from failure.
The FAA incident was particularly revealing. The US government had already documented serious weaknesses in its air traffic control infrastructure. A 2024 Government Accountability Office investigation classified 51 of 138 systems as unsustainable and another 54 as potentially unsustainable.
Meanwhile, a September 2026 investigation identified major weaknesses in the planning and coordination of the FAA’s multibillion-dollar modernization program.
These incidents point toward a larger economic concern.
As banking, transportation, healthcare, telecommunications, government services and artificial intelligence become increasingly interconnected, operational failures can propagate far beyond the systems in which they originate.
Digital infrastructure resilience is no longer simply a technical concern. It is becoming a question of national economic security.
Table of Contents
- Two Disruptions, One Fundamental Warning
- What Actually Happened to America’s Airports?
- The Technical Failure Behind the Ground Stop
- A Vulnerability the Government Already Knew About
- Did New Technology Contribute to the Failure?
- The Redundancy Problem: When Backup Systems Are Not Enough
- The Modernization Challenge: Why Money Alone Cannot Fix the Problem
- Was This a Cyberattack?
- The Economic Consequences of a Four-Hour Shutdown
- Microsoft and the FAA: Different Failures, Common Vulnerabilities
- The Bigger Picture: When Digital Failures Become Economic Crises
- The Investment Opportunity in Infrastructure Resilience
- Why Latin America Should Pay Attention
- Conclusion: We Need to Redesign Resilience Into the Digital Economy
1. Two Disruptions, One Fundamental Warning
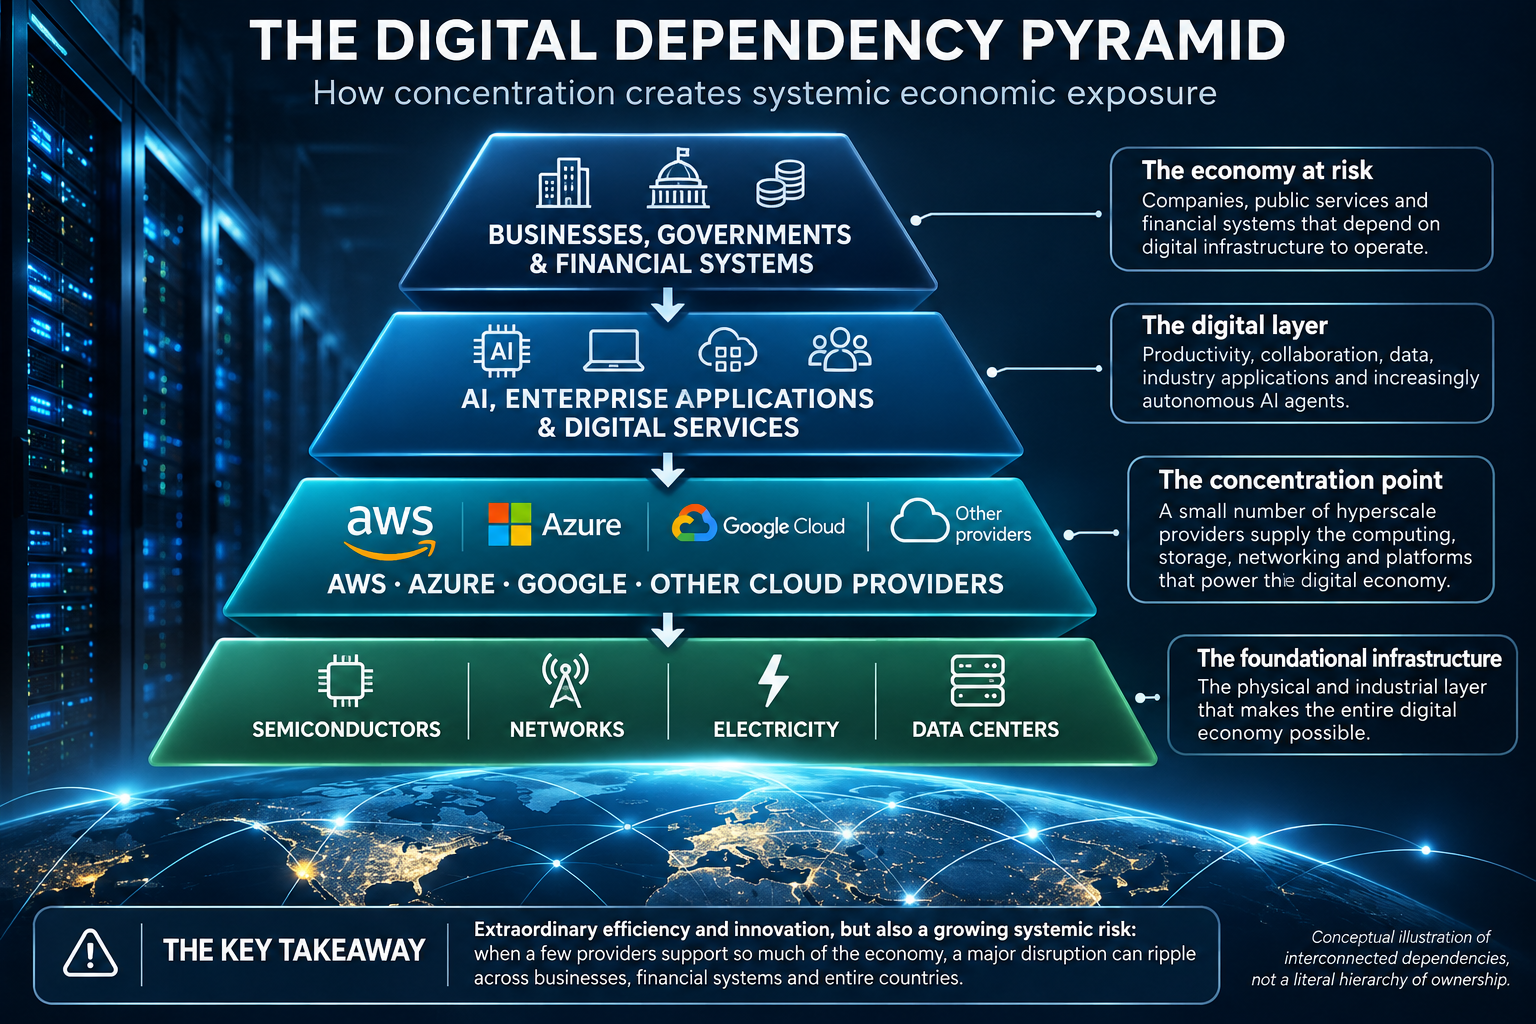
In my previous article, The Hidden Fragility of the Digital Economy, I examined whether the growing concentration of cloud infrastructure among Microsoft, Amazon and Google is creating a new form of systemic economic risk.
The argument was straightforward.
We have spent two decades moving enormous portions of the global economy onto increasingly interconnected digital platforms.
The benefits have been extraordinary: lower costs, greater efficiency, global connectivity, scalability and unprecedented access to computing power.
But there is another side to that transformation.
The more interconnected our systems become, the greater the potential consequences when critical infrastructure fails.
The Microsoft disruption of November 12 illustrated the vulnerabilities of globally interconnected commercial cloud services.
Just one day later, an entirely different incident demonstrated that the same broader concerns extend into national transportation infrastructure.
On November 13, the FAA ordered a nationwide ground stop across the United States.
It was an extraordinary event.
The immediate problem was not an airline reservation system, airport terminal computer or defective aircraft.
It involved telecommunications infrastructure supporting the nation’s air traffic control system.
And it raised a disturbing question:
How can one of the world’s most sophisticated aviation systems remain vulnerable to equipment that its own government has repeatedly identified as technologically unsustainable?
2. What Actually Happened to America’s Airports?
According to the US Department of Transportation, instability in radar and communications systems began at approximately 3:36 p.m. Eastern Time on November 13.
The FAA subsequently ordered a nationwide ground stop as a safety precaution.
Air traffic controllers were experiencing intermittent problems with the telecommunications systems supporting radar information and communications.
Aircraft already in flight were allowed to continue under established safety procedures.
The FAA did not completely lose its radar or communications capabilities. Nevertheless, the instability created unacceptable operational uncertainty.
Transportation Secretary Sean Duffy explained that the FAA could not tolerate situations in which controllers might be unable to communicate reliably or immediately establish an aircraft’s position.
At 8:15 p.m. Eastern Time, the FAA announced that US airspace had reopened.
But reopening airspace did not mean airline operations immediately returned to normal.
Aircraft were out of position. Flight crews were scattered across airports. Passengers were stranded, and airline schedules had been severely disrupted.
The consequences extended well beyond the hours during which departures were restricted.
This distinction is important.
Restoring a failed infrastructure component is not the same as restoring the economic system that depends on it.
3. The Technical Failure Behind the Ground Stop
The initial explanation from US officials focused on aging telecommunications equipment.
Transportation Secretary Duffy identified instability involving legacy switches and routers operating within the FAA’s Time-Division Multiplexing (TDM) telecommunications environment.
TDM is an established technology that allows multiple communications signals to share transmission capacity by allocating time intervals.
Although TDM itself is not inherently unreliable, much of the FAA’s associated equipment and supporting infrastructure is decades old.
According to Duffy, older switches and routers became overloaded with data and began delivering inconsistent information.
The problem affected communications and radar-data systems used by air traffic control facilities.
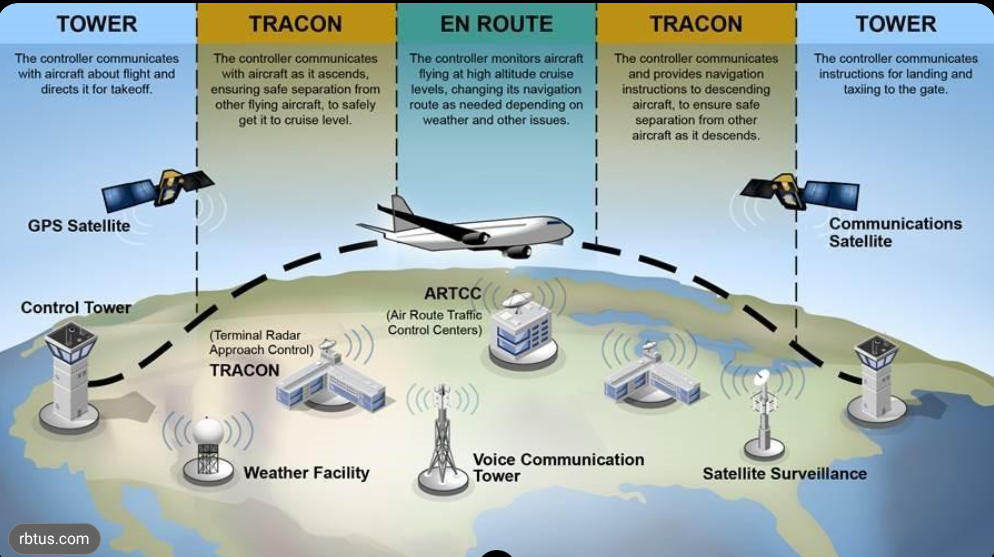
To understand why this matters, consider the structure of US air traffic control.
Airport control towers manage aircraft movements at and immediately around airports.
Terminal Radar Approach Control facilities, known as TRACONs, coordinate aircraft approaching and departing airports within larger terminal areas.
Air Route Traffic Control Centers manage aircraft flying across broad geographical regions.
These facilities must continuously exchange reliable information.
Their communications networks are not simply administrative conveniences. They are essential components of aviation safety.
When information becomes inconsistent or unreliable, the consequences can be immediate.
The FAA’s decision to stop departures was therefore a precautionary response to uncertainty within a safety-critical network.
The exact initiating event behind the November 13 telecommunications instability remains under investigation.
That distinction matters. Officials have identified the equipment involved and described its behavior, but that does not yet establish the complete technical root cause.
4. A Vulnerability the Government Already Knew About
Perhaps the most troubling aspect of the FAA incident is that the underlying infrastructure problems were not new.
In September 2024, the US Government Accountability Office published an investigation into the condition of FAA air traffic control systems.
The findings were remarkable.
Of 138 systems examined:
- 51 were classified as unsustainable.
- 54 were classified as potentially unsustainable.
- Only 33 fell outside those two categories.
In other words, approximately 76% of the systems examined were considered either unsustainable or potentially unsustainable.
Some systems relied on outdated functionality, scarce replacement parts and technology that was increasingly difficult to maintain.
The GAO also identified modernization projects expected to take another 10 to 13 years, while other systems requiring attention lacked modernization plans.
These findings do not establish that every deficient system contributed to the November incident.
But they demonstrate that the FAA’s technological vulnerabilities had been documented long before the nationwide ground stop.
This raises a much broader issue.
Governments and corporations frequently recognize infrastructure vulnerabilities years before they become major operational crises.
Why, then, does modernization so often remain incomplete?
Part of the answer involves cost.
But another part involves institutional complexity, procurement, organizational priorities, operational disruption and the difficulty of replacing technology that must remain available while it is being modernized.
The cost of modernization is visible in a budget. The cost of not modernizing often remains invisible until something fails.
5. Did New Technology Contribute to the Failure?
There was considerable discussion about whether recently introduced technology contributed to the FAA disruption.
Some initial statements suggested that newer systems may have increased pressure on older infrastructure.
However, Transportation Secretary Duffy subsequently clarified that the newer IP-based equipment installed as part of the modernization effort had not experienced the same failure.
He also stated that the FAA’s new SMART air traffic management tool was not connected to the affected systems in a way that could have caused the incident.
This is important because modernizing a complex infrastructure network creates significant integration challenges.
Legacy systems must operate alongside newer equipment, often for extended periods.
Compatibility, traffic management, system interfaces and migration planning become critical.
However, it would be premature to conclude that modernization itself caused the November 13 failure.
The precise triggering mechanism has not yet been established publicly.
What the incident does illustrate is the difficulty of operating a national infrastructure network containing multiple generations of technology.
Modernization is not simply replacing an old switch with a new one.
It requires redesigning and validating the architecture connecting thousands of components.
6. The Redundancy Problem: When Backup Systems Are Not Enough
One of the most important lessons from infrastructure engineering is that having a backup system does not necessarily mean having an independent system.
A previous FAA incident illustrates the problem.
In September 2026, a telecommunications circuit serving an air traffic control facility in the Philadelphia area experienced problems.
The FAA’s contractor switched to a backup fiber-optic line.
A construction crew subsequently damaged that backup line in New Jersey.
The combined problems contributed to disruptions affecting approximately 9,500 flights.
The incident demonstrated how multiple failures can combine to defeat what appears to be a redundant architecture.
The lesson extends far beyond aviation.
Consider a company operating applications in two cloud environments.
It may believe it has diversified its infrastructure.
But what if both environments depend on the same identity provider?
What if both use the same telecommunications carrier?
What if their backups are controlled by the same administrator credentials?
What if the same software vulnerability affects both systems?
The company may have multiple suppliers without having truly independent recovery capabilities.
This is known as common-mode failure.
And it is one of the most important concepts in understanding systemic digital infrastructure risk.
Redundancy is not measured by how many backup systems exist. It is measured by whether those systems can survive the same failure independently.
7. The Modernization Challenge: Why Money Alone Cannot Fix the Problem
The United States has committed substantial resources to modernizing its air traffic control infrastructure.
Congress appropriated $12.5 billion in July 2025 to support the FAA’s modernization program.
Yet a September 2026 GAO investigation identified serious weaknesses in the program’s planning and coordination.
The agency found that the modernization initiative lacked a reliable comprehensive lifecycle cost estimate.
It also found that, as of May 2026, the FAA had 11,389 individual project schedules that were not integrated into a coordinated master schedule.
Think about the implications.
Thousands of individual infrastructure projects were being planned without a fully integrated schedule capable of coordinating dependencies, installation activities and potential operational conflicts.
The GAO warned that this could lead to repeated work at the same facilities, unnecessary operational disruptions, delays and cost overruns.
The first phase of the modernization program is targeted for completion by December 2028.
But without comprehensive planning, accelerating the installation of new technology could introduce additional risks.
This illustrates a fundamental principle.
Infrastructure modernization is not simply a financial problem.
It is an architectural and management problem.
Governments can allocate billions of dollars to new equipment.
But without proper systems engineering, integration, testing, scheduling and accountability, those investments may fail to deliver the resilience they were intended to create.
8. Was This a Cyberattack?
As of November 14, US officials had reported no evidence that the FAA incident was caused by malicious cyber activity.
The Department of Homeland Security indicated that the available information pointed toward a technical problem, while emphasizing that the investigation was continuing.
This distinction is important.
Not every major digital infrastructure failure is a cyberattack.
Failures can result from obsolete equipment, software defects, configuration errors, telecommunications problems, excessive system load or human mistakes.
In many cases, these operational failures can produce consequences comparable to those associated with deliberate attacks.
There is also an important question concerning private contractors.
The FAA relies on external companies for significant portions of its telecommunications infrastructure and modernization activities.
Reuters reported that airline officials had identified a telecommunications network overseen by L3Harris Technologies as potentially relevant to the incident.
That reporting does not establish responsibility or causation.
The broader concern is the complexity of the relationships among government agencies, contractors, telecommunications providers and technology suppliers.
When something fails, identifying exactly who controls each component, who is responsible for maintaining it and who can restore it becomes critically important.
Operational accountability is part of infrastructure resilience.
9. The Economic Consequences of a Four-Hour Shutdown
The immediate effects of the FAA ground stop were substantial.
Aviation analytics company Cirium estimated that approximately 11,000 flights carrying more than 1.5 million passengers were scheduled to depart US airports after 4 p.m. Eastern Time on November 13.
These figures represent scheduled activity exposed to disruption, not the number of passengers confirmed stranded.
By early evening, hundreds of flights had been diverted, and thousands of delays and cancellations were being reported.
But the economic impact was much broader than the number of delayed passengers.
Airlines faced disrupted aircraft rotations, crew availability problems, missed connections and schedule recovery costs.
Airports experienced operational congestion.
Cargo transportation was affected.
Businesses faced interrupted travel and logistical delays.
Passengers incurred additional expenses and lost productive time.
Even after the FAA restored the affected infrastructure, the aviation system needed time to recover.
This is a classic example of cascading economic consequences.
The original failure may occur in one technological component.
But the disruption spreads into many separate economic activities that depend on it.
The resulting losses may continue accumulating long after the original technical problem has been resolved.
10. Microsoft and the FAA: Different Failures, Common Vulnerabilities
The timing of the Microsoft and FAA disruptions invites comparison.
However, we should be precise.
There is no established evidence that the incidents were technically connected.
Microsoft attributed its November 12 disruption to an issue introduced during an earlier network capacity upgrade that surfaced following a subsequent network change.
The company said the incident was not related to cyber activity or AI agents.
The FAA incident involved instability within aging telecommunications infrastructure supporting air traffic control.
Different systems.
Different operators.
Different technical circumstances.
But they expose several common vulnerabilities.
First, modern economies depend on complex technological networks whose internal dependencies are often poorly understood outside the organizations operating them.
Second, a failure affecting shared infrastructure can disrupt multiple services simultaneously.
Third, restoring technical operations does not immediately restore all the businesses and activities affected by the disruption.
Fourth, redundancy and independent recovery capabilities are essential.
And finally, technological sophistication does not necessarily guarantee resilience.
Microsoft represents a highly advanced global commercial technology ecosystem.
The FAA operates a safety-critical national infrastructure network containing both modern and legacy technologies.
Both illustrate the economic importance of understanding and managing shared technological dependencies.
The issue is not that all infrastructure should be decentralized or that cloud computing is inherently unsafe.
The issue is whether critical systems have been designed to fail safely, recover independently and continue essential operations when individual components become unavailable.
11. The Bigger Picture: When Digital Failures Become Economic Crises
The aviation incident brings us back to the larger question raised in my previous article.
Could the failure of critical digital infrastructure become a systemic economic event?
Consider the sectors increasingly dependent on interconnected digital systems:
Banking and financial markets.
Electricity generation and distribution.
Telecommunications.
Transportation and logistics.
Healthcare.
Government services.
Manufacturing and industrial operations.
Artificial intelligence.
Each sector has its own technology infrastructure.
But they are increasingly dependent on shared cloud providers, telecommunications networks, identity systems, software platforms and energy supplies.
A disruption in one sector can therefore affect another.
A telecommunications failure can interrupt financial transactions.
An electricity failure can disable data centers.
A cloud disruption can affect logistics platforms.
A failure in a common identity service can prevent employees from accessing otherwise operational systems.
And as AI agents begin executing more business processes autonomously, these dependencies will become even more consequential.
We should not assume that every outage will produce an economic crisis.
But we should recognize that digital infrastructure failures can become economic shocks, particularly when they affect essential services or coincide with other periods of financial or operational stress.
The challenge is to identify these vulnerabilities before they produce cascading consequences.
12. The Investment Opportunity in Infrastructure Resilience
I believe this creates a significant opportunity for entrepreneurs, investors and infrastructure operators.
The opportunity is not necessarily to replace Microsoft, Amazon or Google.
Nor is it simply to build additional data centers.
The opportunity is to develop the technologies and services that allow organizations to operate when their primary infrastructure becomes unavailable.
Several areas deserve particular attention.
Independent disaster recovery: Systems capable of restoring critical operations without relying on the infrastructure that originally failed.
Multi-cloud orchestration: Software and services that enable organizations to operate across different providers and migrate critical workloads.
Alternative identity and authentication: Independent access mechanisms that preserve essential operations during primary identity-system failures.
Edge computing: Local computing capabilities that allow critical industrial and operational processes to continue functioning when remote connectivity is interrupted.
Infrastructure dependency mapping: Platforms that identify hidden relationships among suppliers, networks, cloud providers and software components.
Operational resilience testing: Services that simulate failures and validate whether businesses can actually recover.
Sovereign and regional infrastructure: Computing and communications services that reduce dependence on distant infrastructure or foreign jurisdictions for selected critical workloads.
These opportunities are not without challenges.
Building resilient infrastructure requires substantial engineering, security, operational discipline and, in some cases, significant capital.
But the potential market extends across virtually every major industry.
Resilience could become a distinct and increasingly valuable category of infrastructure investment.
13. Why Latin America Should Pay Attention
The implications are especially relevant to Latin America.
Countries such as Chile, Brazil and Mexico are expanding their digital economies, adopting artificial intelligence and modernizing financial, industrial and government systems.
Yet much of the technology supporting these activities depends on infrastructure controlled by companies headquartered outside the region.
That does not mean foreign infrastructure is inherently unreliable.
It means countries should understand the operational, legal and geopolitical dependencies created by their technology choices.
Chile presents an interesting case.
Its mining industry, financial services, telecommunications networks, logistics operations and public institutions increasingly depend on sophisticated digital infrastructure.
Many of these activities are economically critical.
A mining operation, for example, may require continuous connectivity, operational monitoring, industrial control systems and access to centralized data platforms.
A major infrastructure disruption can therefore have consequences far beyond the technology department.
I see an opportunity for Latin America to develop regional resilience capabilities, including independent disaster recovery, local computing, infrastructure monitoring and sovereign data services.
But I would not begin by investing billions in new physical infrastructure.
I would begin by identifying customers with critical operational dependencies and determining what they would pay to reduce those risks.
A software-and-services approach could establish commercial demand before substantial infrastructure investments are required.
This is a practical opportunity for regional technology entrepreneurs, investors and infrastructure operators.
14. Conclusion: We Need to Redesign Resilience Into the Digital Economy
The Microsoft and FAA incidents should not be interpreted as evidence that modern technology is fundamentally unreliable.
On the contrary, our digital infrastructure performs extraordinary tasks every day.
But these incidents remind us that complexity, concentration, aging equipment and interconnected dependencies can create vulnerabilities with consequences extending far beyond the original technical failure.
For decades, the technology industry has prioritized speed, efficiency, scalability and cost.
These remain essential objectives.
But I believe another objective must now receive equal attention.
Resilience.
Not simply the ability to restart a server.
Not simply the existence of backup equipment.
And not simply a contractual guarantee of system availability.
Real resilience means the ability to continue essential operations when critical infrastructure fails.
It requires independent recovery capabilities, interoperability, transparent dependencies, tested contingency procedures and infrastructure architectures designed to contain failures rather than propagate them.
The question is no longer whether major technology systems will occasionally fail.
They will.
The real question is whether our economies can continue functioning when they do.
We have built a world that is more connected than at any time in human history. Now we must ensure that it is not more fragile because of that connectivity.
That may become one of the defining infrastructure challenges of the next decade.
And potentially one of its most important investment opportunities.
Sources & Further Reading
1. US Department of Transportation — Official FAA Ground Stop Briefing, November 13, 2026
2. US Government Accountability Office — Air Traffic Control: FAA Actions Are Urgently Needed to Modernize Aging Systems, September 2024
https://www.gao.gov/products/gao-24-107001
3. US Government Accountability Office — Air Traffic Control Systems: Ambitious New Modernization Effort Needs to Improve Cost and Schedule Planning, September 2026
https://www.gao.gov/products/gao-26-107992
4. Reuters — US Flight Shutdown Exposes Deepening Air Traffic Network Crisis, November 14, 2026
5. Associated Press — Nationwide FAA Ground Stop and Legacy Infrastructure Failure, November 14, 2026
https://apnews.com/article/f81b0904331dafad6133f291e5f531a8
6. Al Jazeera — FAA Ground Stop Lifted: Why Were US Flights Grounded, and What’s Next?, November 14, 2026
7. Microsoft — Official Cloud Service Status and Incident Communications
https://status.cloud.microsoft
8. Microsoft Incident Communications — November 2026 Service Disruption, University of Wisconsin–Milwaukee Service Archive
About the Author
Arturo Duran is a technology strategist with international experience in digital transformation, media, automation, artificial intelligence and emerging technologies.
His work focuses on the intersection of technology, business transformation, investment opportunities and the economic implications of innovation.
Website: www.arturoduran.com
Editorial note: This article reflects information available as of November 14, 2026. The FAA’s complete technical root-cause investigation and Microsoft’s final post-incident report were not yet available. Interpretations concerning systemic risk and investment opportunities represent the author’s analysis.